Typingflow
Accelerate your writing journey with the power of AI!
Project overview
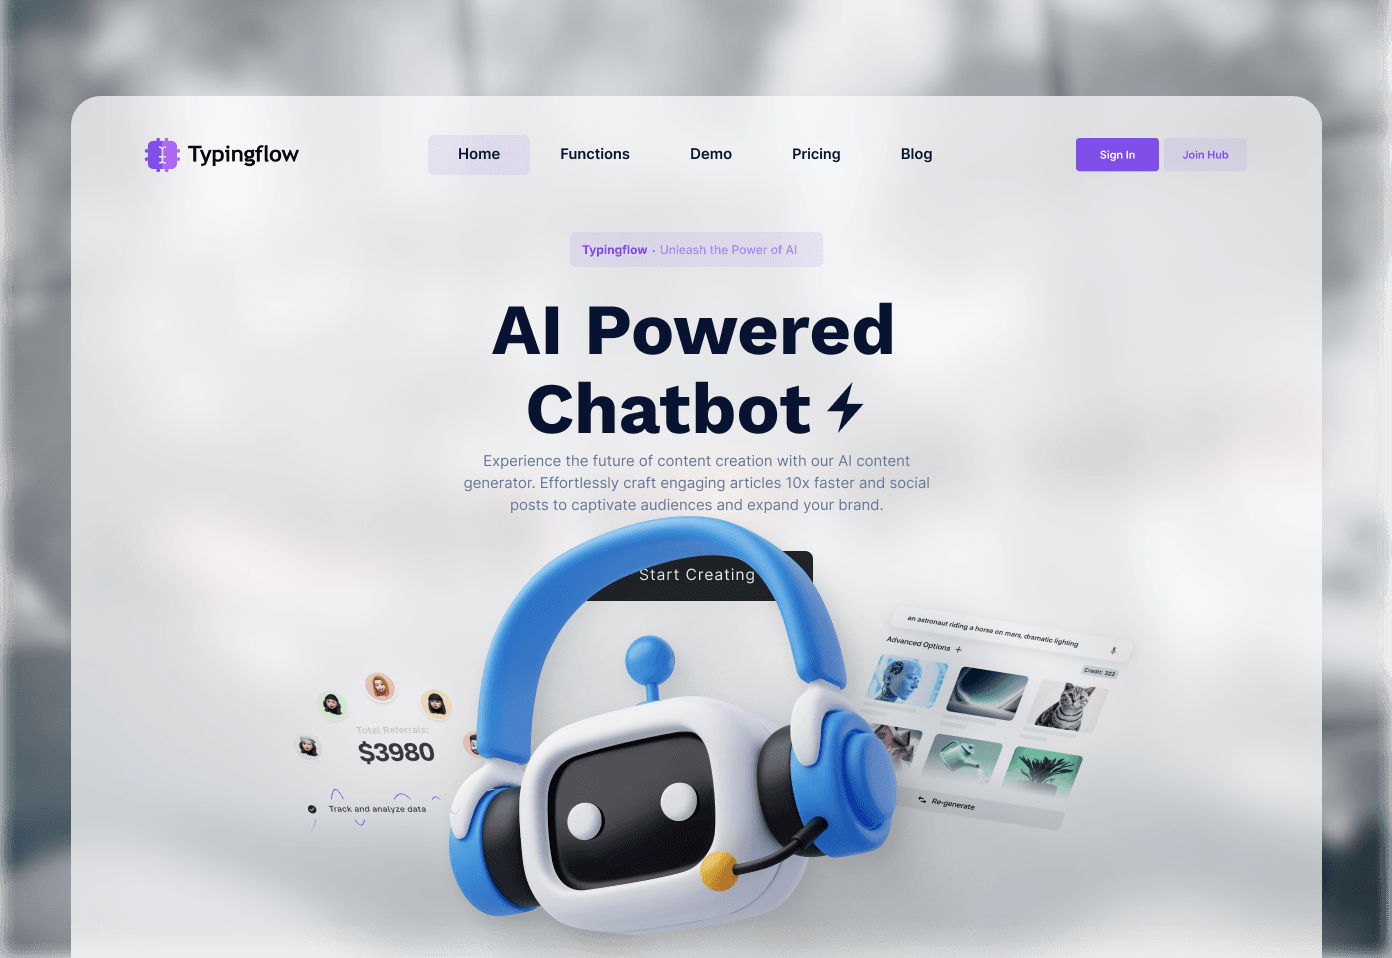
Typingflow is Accelerate your writing journey with the power of AI! Typingflow is engineered to swiftly produce superior-quality content, eliminating strenuous effort on your part. Built with high standards for performance, security, and intuitive user experiences, the platform is engineered to support mission-critical workflows and seamless scale.
What was the problem or pain point
Client Dilemma & Technical Bottleneck
Typingflow set out to build a next-generation AI writing companion and distraction-free text editor that assists authors, marketers, and researchers with real-time text completion, contextual tone adjustments, and factual research. The key engineering obstacles were latency and context continuity: standard OpenAI API calls introduced noticeable 1.5 to 3-second delays that interrupted writing flow, and managing multi-thousand-word document context without exceeding LLM token limits or blowing compute budgets was extremely challenging.
What we suggested to the client
Solid Sphere Architectural Recommendation
Solid Sphere recommended an asynchronous, streaming LLM architecture with intelligent rolling context windows. We proposed building a modern, distraction-free web editor using Next.js, TypeScript, and TailwindCSS, backed by a high-speed Python FastAPI backend that streams token responses over WebSockets with sub-50ms Time-to-First-Token (TTFT) latency, paired with semantic document chunking to provide relevant contextual awareness without bloating prompt tokens.
What made this project challenging
Providing real-time generative writing suggestions without breaking the writer's mental creative flow
Streaming token completions with under 50ms latency using WebSocket bidirectional channels
Supporting customizable author tones (Academic, Journalistic, Creative, Executive) dynamically
Building a distraction-free, minimalist writing canvas with markdown export and history diffing
What was implemented and how it was implemented
Step-by-Step Technical Execution
We built a minimalist, typography-focused writing application using Next.js and TailwindCSS, implementing a custom rich text editor with markdown shortcuts and keyboard-driven command palettes (like Slash commands). We engineered a streaming backend in FastAPI that interfaces directly with OpenAI and Anthropic LLM models using Server-Sent Events (SSE) and WebSockets. As the user pauses typing, a background worker analyzes the active paragraph and surrounding document headings, retrieving semantically relevant sections from an in-memory vector cache to prime the prompt. Tokens stream into the editor with zero perceived latency, allowing users to accept, reject, or cycle through alternative phrasing with a single keystroke. We also implemented tone transformations, outline generation, and automated bibliography citation lookups.
How we delivered
Developed minimalist rich-text editor with keyboard shortcut navigation and inline ghost-text completions
Engineered low-latency WebSocket streaming proxy connecting browser sessions to LLM backends
Built custom prompt engineering engine tailored to context preservation and author style matching
Implemented local storage auto-save and document revision tracking with instant undo/redo
What did we use to implement it
Technology Stack & Technical Rationale
Next.js and TypeScript provided the high-performance, accessible frontend framework with optimal typography rendering. FastAPI with Python delivered asynchronous, high-throughput streaming endpoints for LLM communication. OpenAI API and Anthropic Claude served as the foundational language models. WebSockets and SSE provided sub-50ms streaming token delivery. TailwindCSS enabled an elegant, distraction-free dark and light writing workspace.
Key outcomes
Sub-40ms average completion streaming response time
Over 50,000 active content writers and novelists
Average daily writing output increased by 2.5x
4.9★ rating across product hunt and writer communities
Have a project like this?
Share your goals and constraints. We'll respond with next steps and a practical proposal.