DataOps by Datalytyx
Better Data Faster | Based on Gitlab Community Edition
Project overview
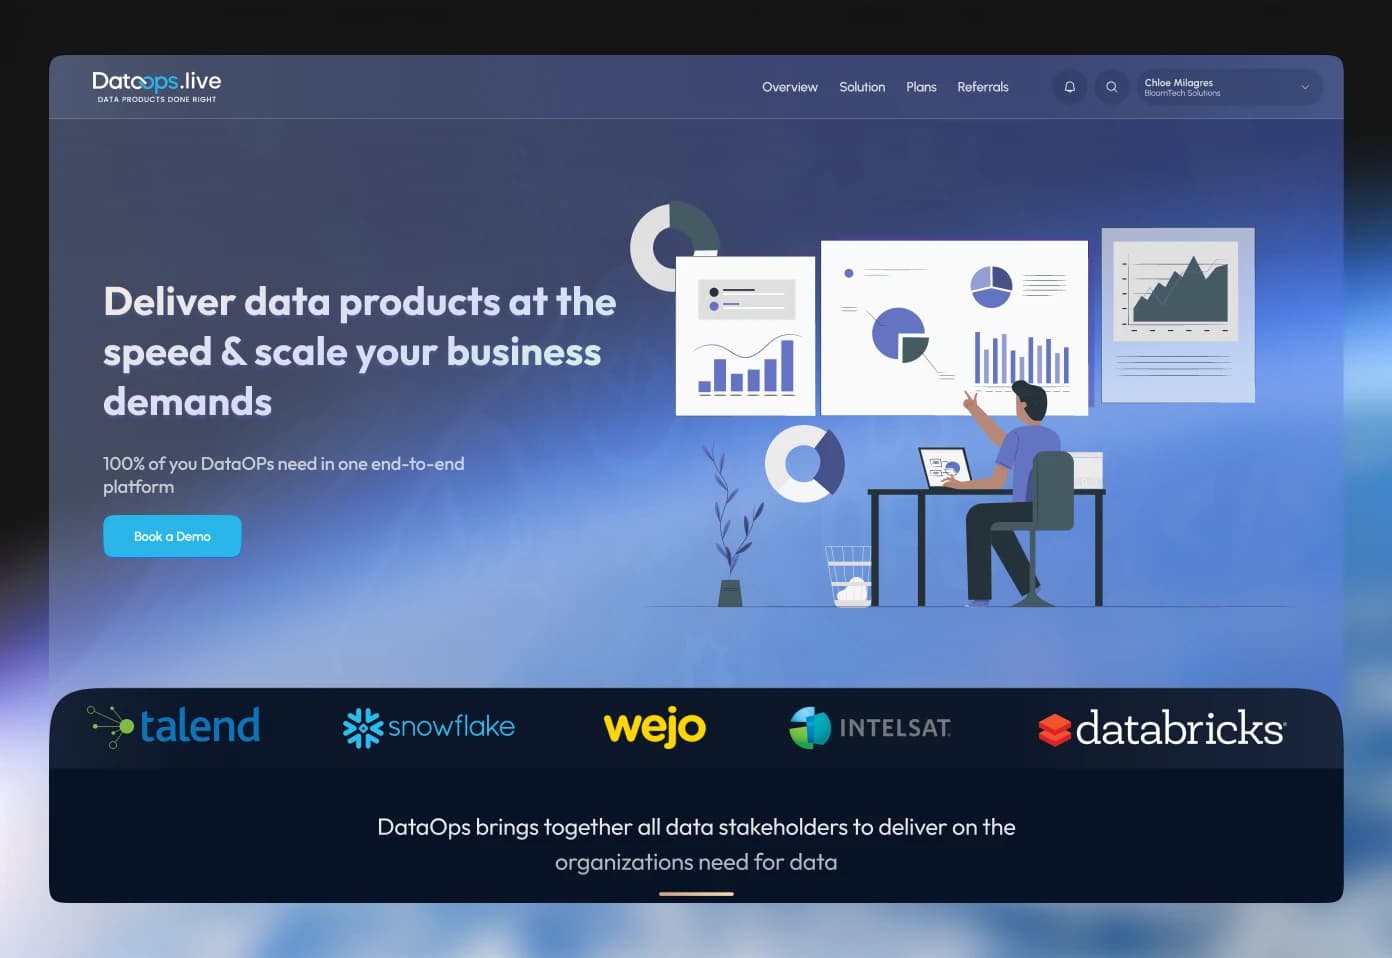
DataOps by Datalytyx is Better Data Faster | Based on Gitlab Community Edition. Extended Gitlab Community Edition Built with high standards for performance, security, and intuitive user experiences, the platform is engineered to support mission-critical workflows and seamless scale.
What was the problem or pain point
Client Dilemma & Technical Bottleneck
Datalytyx (a major data engineering consultancy) needed to help enterprise clients accelerate their cloud data warehouse deployments on Snowflake. Enterprise clients were bogged down by manual, error-prone data pipeline deployments, unversioned SQL transformation scripts, lack of automated testing for ETL workflows, and multi-week release cycles that frequently caused data outages and inconsistent financial reporting across corporate business intelligence tools.
What we suggested to the client
Solid Sphere Architectural Recommendation
Solid Sphere proposed designing an automated, enterprise-grade DataOps CI/CD framework. We recommended creating a repeatable orchestration platform built around GitLab CE, containerized testing harnesses, and Terraform infrastructure-as-code (IaC) that treats database schemas, SQL transformation models (dbt), and Snowflake access roles with the same rigor, version control, and automated testing as enterprise software code.
What made this project challenging
Bridging the gap between software engineering CI/CD best practices and enterprise data pipelines
Automating version control, testing, and deployment of data transformation scripts into Snowflake
Enforcing data governance, lineage tracking, and schema migration validation automatically
Scaling pipeline orchestration across multi-cloud Kubernetes clusters
What was implemented and how it was implemented
Step-by-Step Technical Execution
We architected an end-to-end DataOps automation platform utilizing self-managed GitLab CE pipelines orchestrated on Kubernetes. We wrote modular Python automation scripts and Terraform templates that dynamically provision ephemeral Snowflake testing databases for every git pull request. In these ephemeral environments, our automated test suite compiles dbt models, runs data quality checks (null validations, referential integrity, schema drift detection), and verifies security role policies before any code can merge into production. Once approved, the pipeline automatically deploys zero-downtime schema migrations and updates Snowflake data shares without interrupting active BI dashboards. We also built an intuitive management web interface allowing non-technical data stewards to monitor pipeline runs, view schema diffs, and audit access logs.
How we delivered
Extended GitLab Community Edition with custom DataOps pipeline runners and validation triggers
Engineered automated data quality testing framework checking row counts, nulls, and anomalies
Built Dockerized pipeline execution environments with parameterized Terraform configurations
Developed enterprise web dashboard displaying pipeline health, test coverage, and execution history
What did we use to implement it
Technology Stack & Technical Rationale
GitLab CE and Kubernetes formed the foundation for automated CI/CD pipeline orchestration and container runner execution. Python was used to build custom pipeline CLI utilities, data validation test suites, and Snowflake connector bridges. Snowflake served as the cloud data warehouse target platform. Terraform codified all cloud infrastructure, IAM permissions, and Snowflake warehouse sizing. Docker ensured isolated, reproducible testing environments for every data transformation build.
Key outcomes
Reduced data pipeline deployment cycle from weeks to minutes
Eliminated 90% of production data bugs via automated pre-commit tests
Adopted by FTSE 100 enterprise data teams
End-to-end auditability and data governance compliance
Have a project like this?
Share your goals and constraints. We'll respond with next steps and a practical proposal.